Academic research · Web Scraping
SSRN Research Papers and Authors Dataset
Built by Van Data Team for Academic research client
A scraper that works behind SSRN's anti-bot layer and delivers paper metadata with 43 fields per paper, linked to author profiles and citations, in two CSV batches: 239,037 papers and 198,523 authors.
- papers delivered, 43 fields each
- 239,037
- author profiles linked
- 198,523
Measured outcomes
Outcome 01
239,037 papers and 198,523 authors delivered in two CSV batches
Outcome 02
43 fields per paper, from downloads and abstract views to rank and citations
Outcome 03
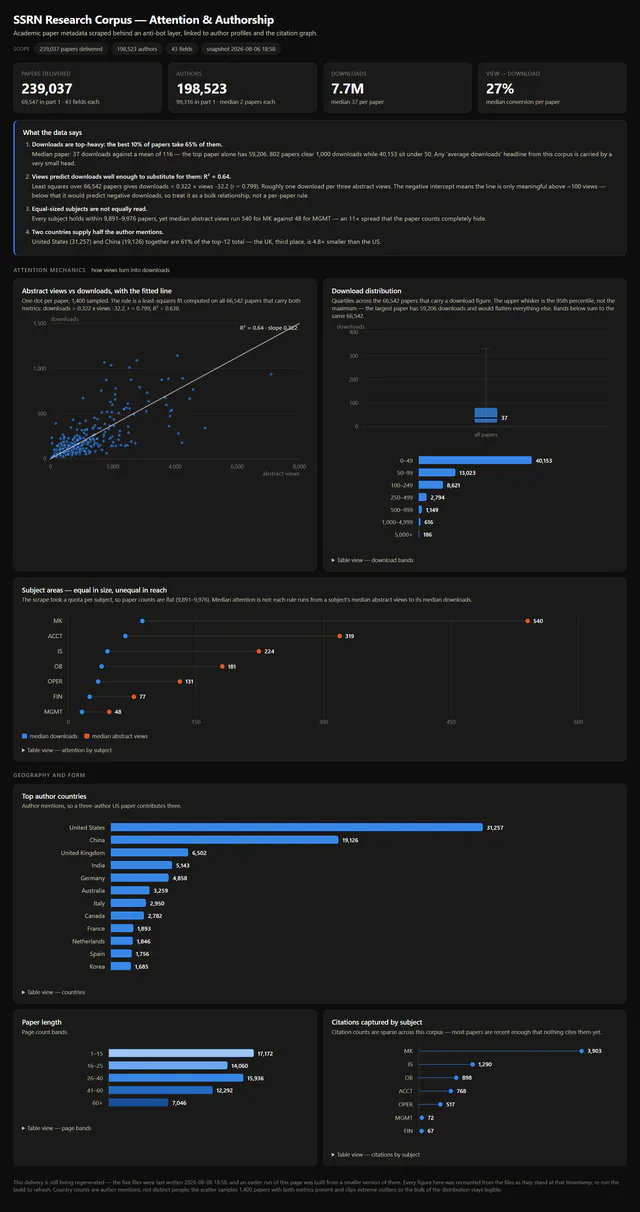
Top 10% of papers take 65% of 7.7 million downloads
Challenge pressure
SSRN shows each research paper's downloads, abstract views, rank and citations on its own page, behind an anti-bot layer. The client needed that metadata for hundreds of thousands of papers, linked to author profiles and the citation graph.
The situation
Each SSRN paper page shows its downloads, abstract views, download rank, citation count and author keywords, and each author has a profile of their own. Read at scale, those pages show how research attention is distributed, but only once they are collected, linked and counted.
What we built
The scraper collects paper pages behind the anti-bot layer and links each paper to its authors and citations. The papers came in two CSV batches, 239,037 rows with 43 fields each (2.8 GB), alongside 198,523 author records. The source kept growing while the dashboard was being built (papers rose from 211,022 to 239,037 and downloads from 4.9 million to 7.7 million), so every figure on this page was recounted against the 6 August 2026 snapshot.
What changed
The client receives paper-level metrics at full scale: 7.7 million downloads, a median of 37 per paper. The dashboard shows how unevenly attention falls: the top 10% of papers take 65% of downloads, views predict downloads well enough to stand in for them (R² = 0.64 over 66,542 papers, about one download for every three abstract views), and subjects of equal size are not read equally, with median abstract views of 540 in MK against 48 in MGMT.
Constraints and decisions
Rows are kept as delivered: a duplicated paper ID is flagged, a missing downloads figure stays empty rather than imputed, and papers written in Vietnamese keep their diacritics. Country counts are author mentions, not distinct people, and the charts cover the first batch. Only paper-level public metadata is shown here, without author names, abstracts or DOIs.
Technology stack
Need a similar system?
If this case study maps to your current workflow, the next useful step is a scoped project conversation with constraints, timeline, and integration needs.
Related case studies
More work like this
Recruiting
Cybersecurity Job Listings from Dice.com
500
Dice.com listings, 23 fields each
Social and brand
LinkedIn Company Posts and Engagement Dataset
15,192
posts from 12 company pages
E-commerce
B2B IT Hardware Catalogue with Translated Descriptions
72,685
SKUs across 319 brands